Dr Robert W Harrison is an emeritus professor of computer science at Georgia State University. His research background is in scientific computing and bioinformatics. He has published 256 reviewed papers and proceedings in areas ranging from molecular modelling and simulation to inverse problems and machine learning. His first employment after receiving his PhD from Yale University in 1985 in Molecular Biophysics was as a programmer for Intelsat working on convolutional codes and the simulation of satellite communication channels, which demonstrates the wide breadth of his interests and skills. Since then he has been at NBS (NIST), Frederick Cancer Research and Development (NCI), Thomas Jefferson University and for the last 23 years at Georgia State University. His most recent research has been studying imprecise or “Fuzzy” machine learning and efficient implementations using restricted Boltzmann machines. His highly efficient algorithms for these machines are two to three thousand times faster than conventional algorithms on test data sets. He has developed algorithms for continuous Boltzmann machines that exhibit quadratic convergence in the worst cases. Implementations of these algorithms can be applied to recognition of time-series and image data.
Abstract: One of the key strengths of Restricted Boltzmann Machines (RBMs) is their ability to recognize and reproduce patterns or sequences in data. Our group has developed efficient algorithms for training RBMs and demonstrated that integrating RBMs with fuzzy methods provides an effective approach for handling noisy and incomplete data. A remaining challenge is the development of highly efficient methods for applying RBMs to large-scale datasets.
Since the evaluation of the energy function and the selection of the best RBM from a set of models essentially involve vector dot products, this work explores the use of convolution operations and the Fast Fourier Transform (FFT) to reduce the computational complexity of energy evaluation from O(N²) to O(N log N). We refer to this approach as Convolutional RBMs.
This study evaluates the performance of Convolutional RBMs in recognizing features within very large images of size 10,000 × 10,000 pixels. The images are derived from LIDAR (Light Detection and Ranging) data for the United Kingdom. LIDAR data consist of a 1-meter grid representing land surface elevation obtained from airborne surveys covering a 10 km × 10 km area. Extracting and labeling features in these datasets is an important step in identifying archaeological structures and assessing human impact on the landscape.
Dr. Koichi Takeuchi is an Associate Professor at the Graduate School of Environmental, Life, Natural Science and Technology, Okayama University. He received his Ph.D. from the Nara Institute of Science and Technology in 1998 and subsequently worked as an Assistant Professor at the National Institute of Informatics. From 2002 to 2003, he conducted research at INRIA Lorraine in France as an invited researcher. He joined Okayama University in 2003 and has been serving as an Associate Professor since 2021. His current research interests include automatic essay grading, predicate–argument structure analysis, text mining, terminology extraction, and the application of language models in the medical field.
Abstract: :
Semantic Role Labeling (SRL), derived from linguistically-motivated lexical semantics, provides a deeper level description than basic syntactic structure for analyzing sentence structure.
Understanding this semantic structure enables the structural explanation of causes, conditions, and events expressed within a sentence. This capability is essential for information extraction and text mining when processing large-scale texts.
Currently, two major annotated corpora with semantic role labels are available for English: PropBank proposed in the field of natural language processing and FrameNet proposed in the field of linguistics. However, the development of specific systems and methodologies for assigning semantic role labels to Japanese is still in an active area of research.
In this presentation, we demonstrate NPCMJ-PT, a Japanese semantic role annotation dataset currently under construction. This dataset is based on the NPCMJ (NINJAL Parsed Corpus of Modern Japanese), which provides syntactic analysis of Japanese documents. NPCMJ-PT includes PropBank format and Japanese name semantic role labels and concept frames for approximately 50,000 predicates.
A significant challenge in semantic role assignment is the existence of multiple tag sets, such as thematic roles, PropBank and FrameNet. To address this, NPCMJ-PT defines and assigns two types of semantic roles based on an analysis of Japanese lexical semantics: PropBank-style roles and thematic roles based on Lexical Conceptual Structure.
We will explain the methodology for assigning these semantic roles and present automatic SRL models based on pre-trained language models fine-tuned on NPCMJ-PT. Finally, We will demonstrate the experimental results of these models and discuss the future applicability of semantic role labeling in Japanese.
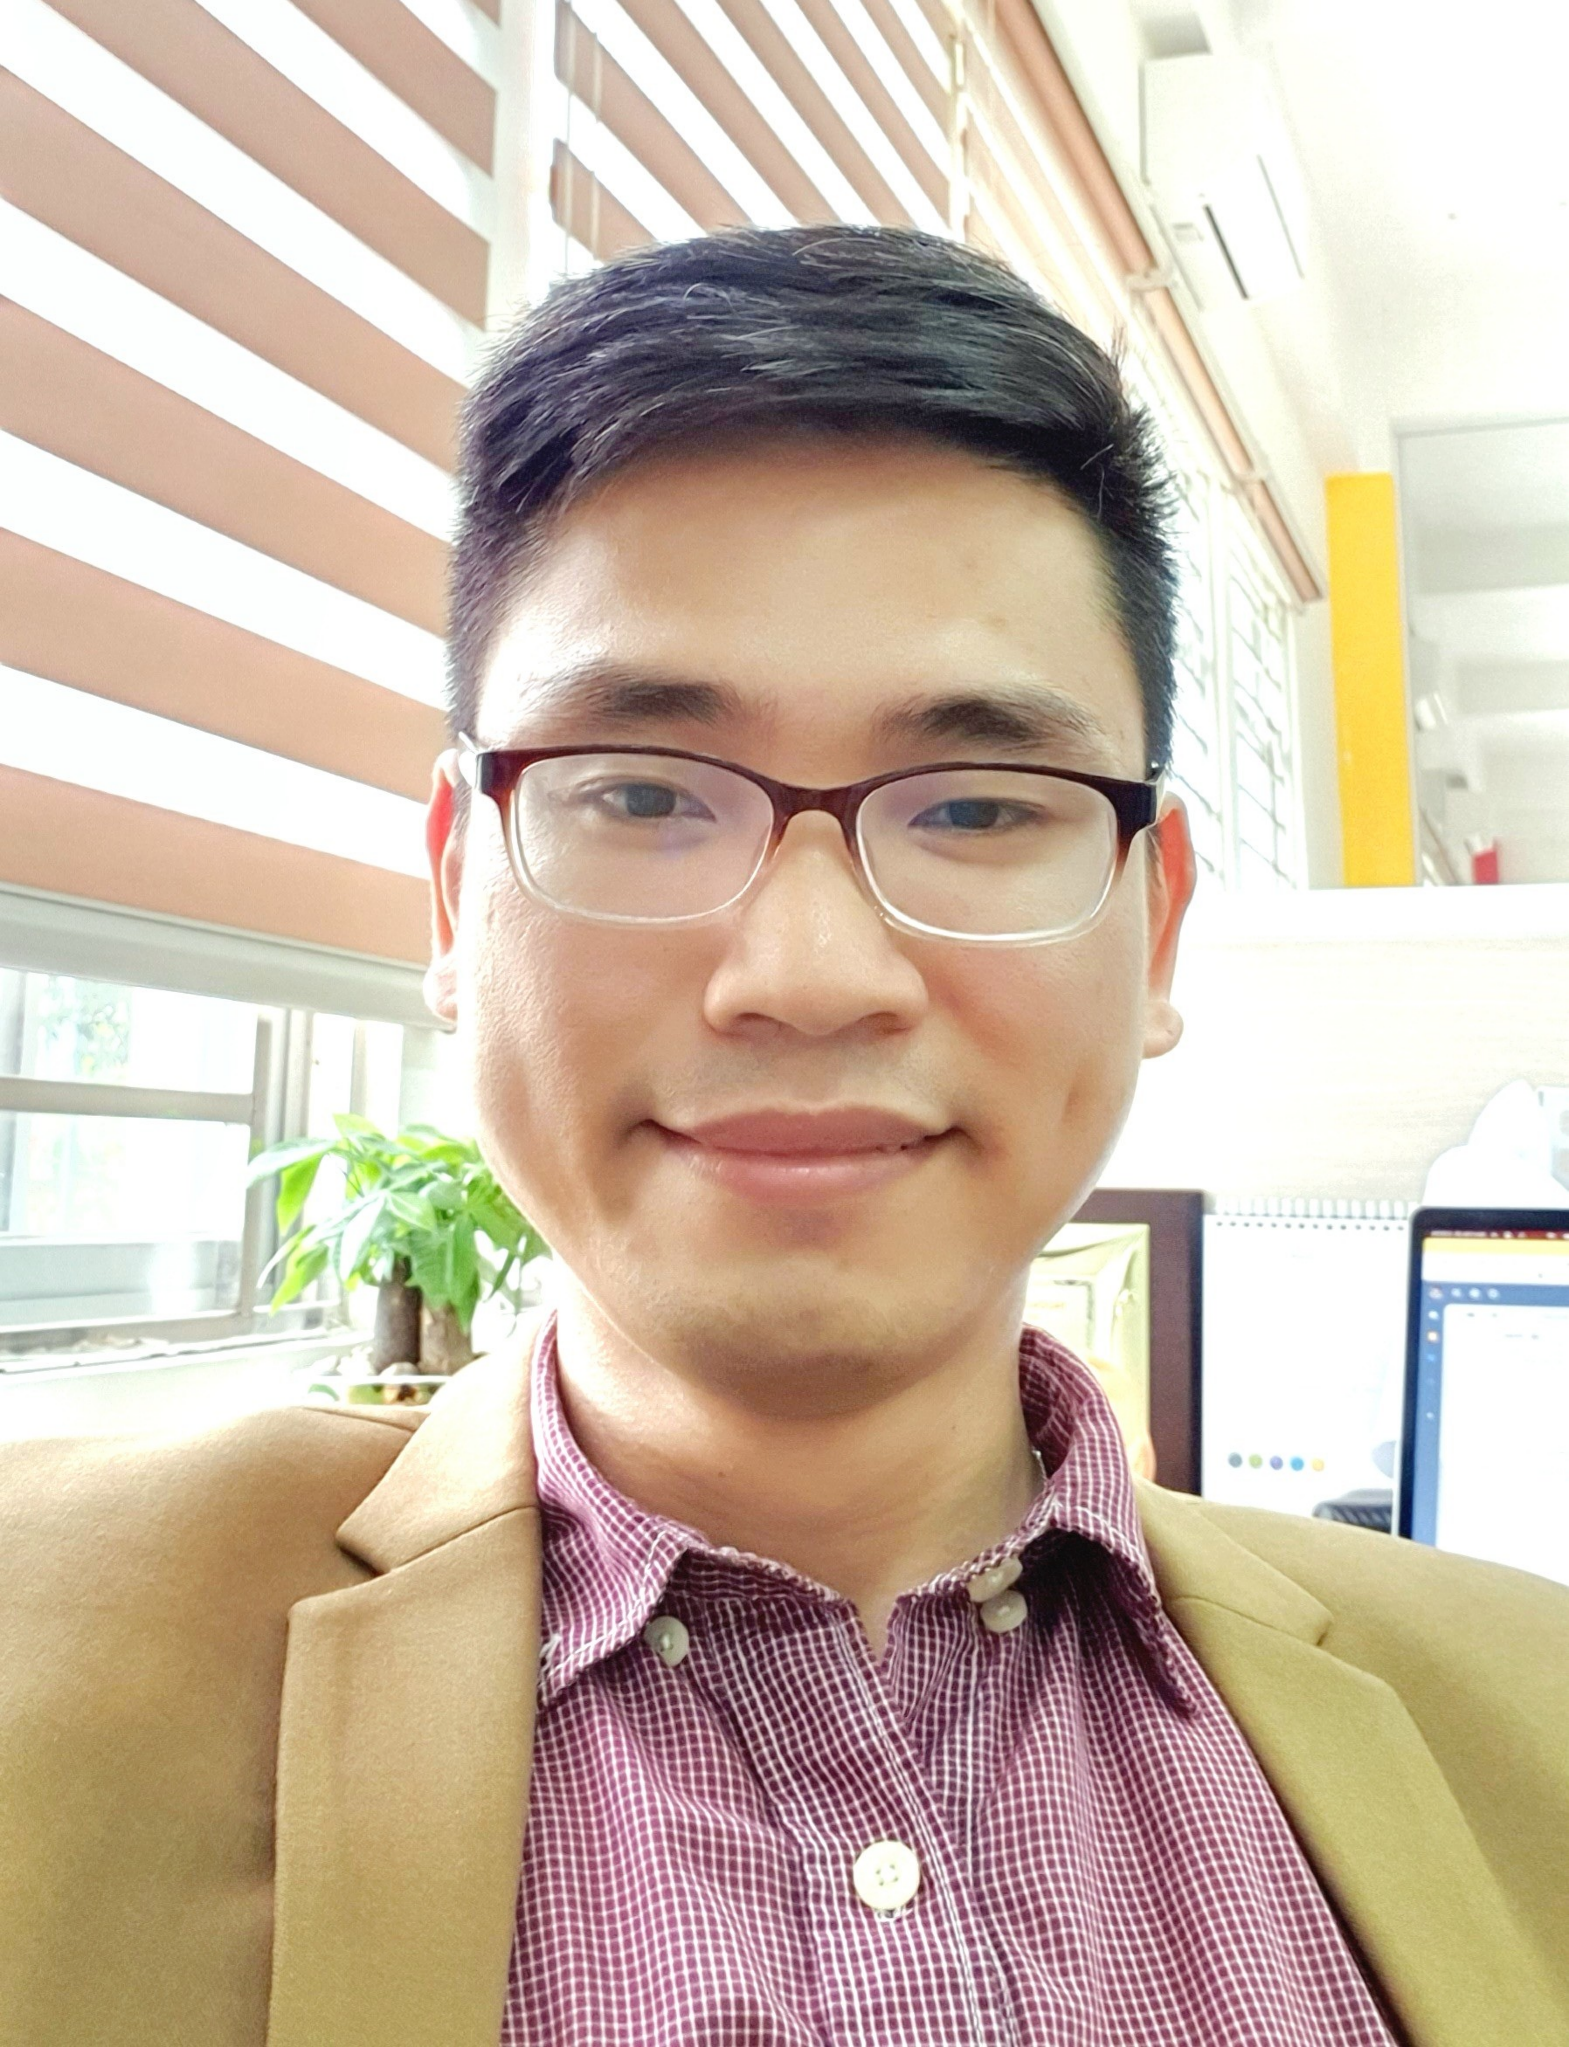
Dr. Nguyen Huu Nhat Minh is Deputy Head of the Department of Science, Technology, and International Cooperation and is in charge of the Research Program at the Digital Science and Technology Institute (eSTI), Vietnam–Korea University of Information and Communication Technology, The University of Danang, Vietnam. He also leads the Intelligent Systems research group at eSTI.He received his Ph.D. in Computer Science and Engineering from Kyung Hee University, South Korea, in 2020, where he subsequently worked as a Postdoctoral Researcher. He has also been a Visiting Scholar at Indiana University South Bend, USA.His research interests include multimodal learning, natural language processing, speech recognition, generative AI, computer vision, federated learning, distributed learning, edge computing, and UAV networks. He has published research in leading ACM and IEEE journals and conferences, including IEEE Transactions on Mobile Computing, IEEE/ACM Transactions on Networking, IEEE Transactions on Wireless Communications, and IEEE Transactions on Neural Networks and Learning Systems. He received the Best KHU Ph.D. Thesis Award in Engineering in 2020. His current research focuses particularly on multimodal federated learning, personalized AI, and democratized learning.
Abstract: :
Emerging cross-device artificial intelligence (AI) applications require a transition from conventional centralized learning systems towards large-scale distributed AI systems that can collaboratively perform complex learning tasks. In this regard, federated learning (FL) lays out a novel learning mechanism for building distributed machine learning systems for multiple clients to collaboratively train a generalized global model without sharing their private data. In this talk, we first cover various designs of FL to cope with different perspectives of FL systems for realizing robust personalized Federated Learning (FL) systems, efficient model aggregation methods for dealing with the consequences of non-i.i.d. properties of client's data, often referred to as statistical heterogeneity and small local data samples from the various data distributions. We developed novel approaches for knowledge transfer between the global model and local models regarding single-modal data as well as multimodal data. Utilizing a variety of recent techniques such as knowledge distillation, contrastive learning regularization, and class-based prototype representation opens a promising direction for transfer knowledge across models.
Second, we then introduce the proposed Democratized learning (Dem-AI) systems which is a holistic framework for building self-regulating scalable distirbuted learning systems extending beyond traditional federated learning. This approach relies on hierarchical self-organization of personalized learning agents through group contribution and hierarchical generalization to enable both specialized and generalized learning processes. Moreover, we also share a brief introduction to the emerging multi-agent communication protocols that enable intelligent agentic collaboration and open fruitful research directions in robotics, autonomous systems, and medical agents. To this end, the talk introduce promising collaborative schemes for future AI agent collaboration across diverse domains, fostering more robust, scalable, and intelligent distributed learning systems.